Does Splunk use Mongodb?
 Christopher Anderson

Considering this, does Splunk use database?
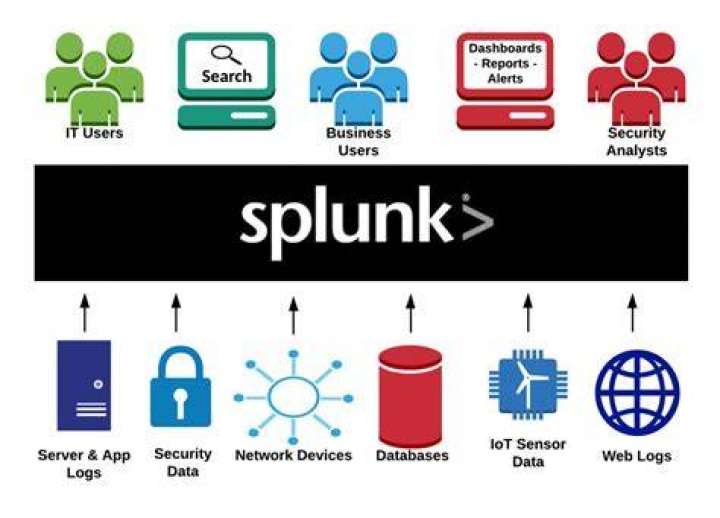
Splunk is an advanced, scalable, and effective technology that indexes and searches log files stored in a system. The main advantage of using Splunk is that it does not need any database to store its data, as it extensively makes use of its indexes to store the data.
Subsequently, question is, does Splunk use SQL? It enables Splunk Enterprise to connect to and exchange data with databases such as MySQL, Microsoft SQL Server, Informix, DB2, and many others, enriching your Splunk Enterprise data by combining it with data that was previously only available to you directly from those databases.
Also to know, what does Splunk use for indexing?
Splunk Enterprise transforms incoming data into events, which it stores in indexes. An indexer is a Splunk Enterprise instance that indexes data. For small deployments, a single instance might perform other Splunk Enterprise functions as well, such as data input and search management.
What technology does Splunk use?
Splunk is a software technology which is used for monitoring, searching, analyzing and visualizing the machine generated data in real time. It can monitor and read different type of log files and stores data as events in indexers. This tool allows you to visualize data in various forms of dashboards.
Who uses Splunk?
We have found 14,346 companies that use Splunk.
Top Industries that use Splunk.
| Industry | Number of companies |
|---|---|
| Computer Software | 4075 |
| Information Technology and Services | 1563 |
| Financial Services | 519 |
| Hospital & Health Care | 475 |
Is splunk easy to learn?
There is no "easy" path to learning Splunk, many people have been working with Splunk for many years and still don't know it all, and it is a cumulation of trial and error, docs reading, and discussions with other Splunkers.Which database is used by Splunk?
MongoDB is used by Splunk to facilitate certain internal functionality like the kvstore but is by no means where data is stored as it is ingested from Universal Forwarders etc. Data that is ingested from external sources all goes to an index as specified in your configuration.Is splunk open source?
Splunk is basically a software platform which is mainly used in the machine-generated data analysis and is also implemented in the data visualization process as per the current industry and market standards. But there is a good amount of costing is associated with its usage and thus it is not an open sourced tool.Is splunk a SIEM tool?
Splunk Enterprise Security (ES) is a SIEM that uses machine-generated data to provide operational insights into security technologies, threats, vulnerabilities and identity information.Does Splunk use Hadoop?
Seamlessly search and analyze Hadoop-based data as part of your Splunk Enterprise deployment with Splunk Analytics for Hadoop. Splunk Analytics for Hadoop gives you the power to rapidly detect patterns and find anomalies across petabytes of raw data in Hadoop without the need to move or replicate data.Is splunk a big data tool?
Yes, splunk is a software of big data. Splunk is a powerful platform for analyzing machine data, data that machines emit in great volumes but which is seldom used effectively.Is splunk a NoSQL database?
Splunk Inc. Oracle NoSQL Database is a scalable , distributed NoSQL database, designed to provide Data can be modeled as relational-database-style tables, JSON documents, RDF TriplesWhat is Splunk architecture?
Splunk Architecture Overview (e-learning) It describes the technologies that are working together in Splunk. Topics covered range from core components (indexes, search heads, knowledge objects), to basic web technologies (URIs, HTML, XML) to languages and frameworks (Python, JavaScript, App Framework).How does Splunk store data in indexer?
Splunk IndexerSplunk instance transforms the incoming data into events and stores it in indexes for performing search operations efficiently. If you are receiving the data from a Universal forwarder, then the indexer will first parse the data and then index it. Parsing of data is done to eliminate the unwanted data.How can I get data from Splunk?
To get data into your Splunk deployment, point it at a data source. Tell it a bit about the source. That source then becomes a data input. Splunk Enterprise indexes the data stream and transforms it into a series of events.What can splunk monitor?
Splunk apps for server monitoring provide deep visibility into faults, events, capacity, configurations and the security of your server environments. Find an app or add-on for most data sources and user needs.How do I send Splunk logs?
Well that's exactly what the Universal Forwarder is for - reading logs on one system and forwarding them to a Splunk instance on another system. The best option is to install a universal forwarder on the server, where the logs are generated. The forwarder can send the logs to the indexer (your primary Splunk server).What are stages of Splunk indexing?
Event processing occurs in two main stages, parsing and indexing. All data that comes into Splunk Enterprise enters through the parsing pipeline as large (10,000 bytes) chunks. During parsing, Splunk Enterprise breaks these chunks into events which it hands off to the indexing pipeline, where final processing occurs.What is Splunk data pipeline?
data pipeline. noun. The route that data takes through Splunk Enterprise, from its origin in sources such as log files and network feeds, to its transformation into searchable events that encapsulate valuable knowledge.How can I learn Splunk?
How to Learn Splunk?- Determine the need for Splunk for you and your organization.
- If applicable - download the software.
- Take the Cybrary Intro to Splunk course.
- Take additional courses through Cybrary or other credible sources available.